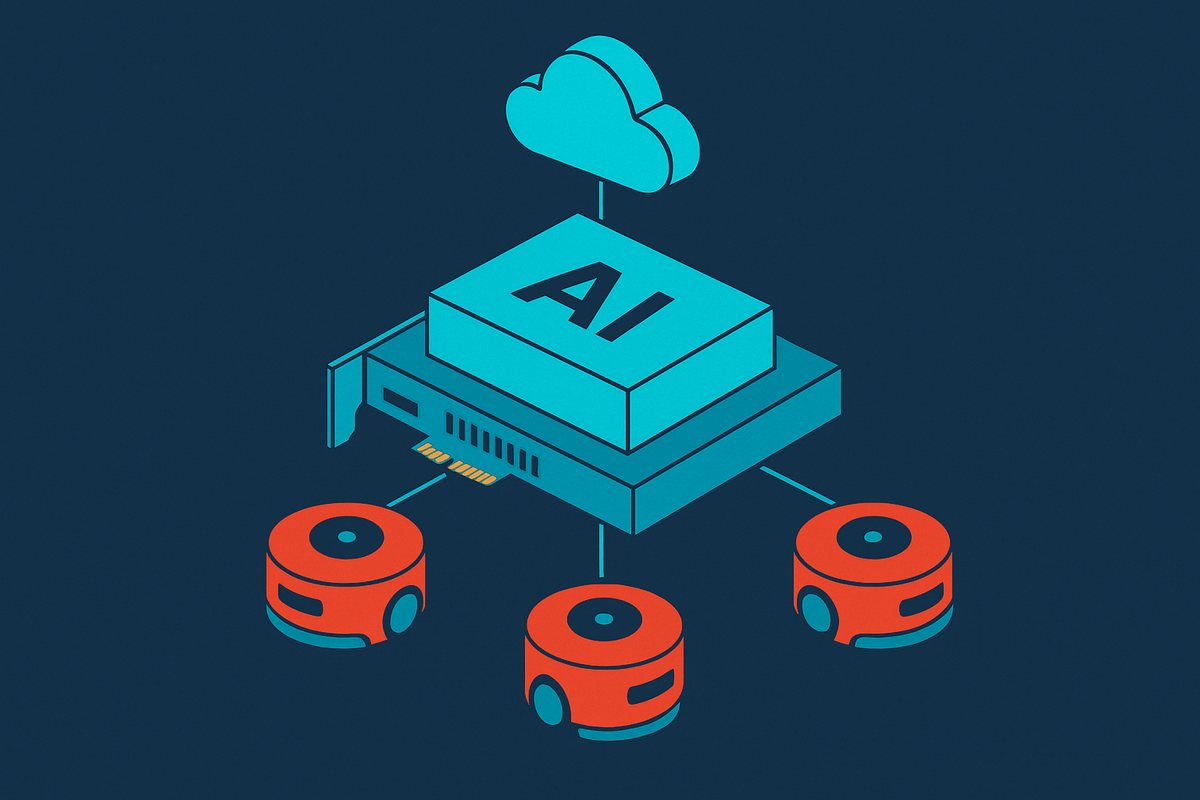
Qualcomm Cloud AI 100 Ultra Inference Card for Robot Fleet Backend Services
The on-site inference tier that makes large language models fast enough for robot fleets.
Adaeze Okonkwo
Staff Writer, Edge AI & Latency
Adaeze Okonkwo has covered embedded systems and IoT deployments since 2019, with a particular focus on the tradeoffs engineers face when pushing inference workloads to resource-constrained devices. Before writing full-time, she contributed hardware teardowns to several independent technical outlets.
1 story
The on-site inference tier that makes large language models fast enough for robot fleets.